Creating a Machine Learning Pipeline
Pre-Requisits
For the pre-requisits, it will be necessary to create a virtual environment…
Set-Up
Checking Virtual Environment
First, we need to check whether we were able to successfully connect to our virtual environment ml-env:
# Check: Is Notebook connected to our `venv`?
import sys
print(sys.executable) # In which environment does this Jupyter Notebook run? --> should be in your `ml-env` that you installed...
/Users/jomaye/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/bin/python
As we can see from the output, the path to our virtual environment is the right one. Hence, we were successfully able to connect our ml-env to this notebook!
Loading the necessary Libraries
# Standard Imports
from src.utils import * # this contains all the traditinional ML-Libraries to build a pipeline, as well as pandas, numpy, matplotlib, seaborn etc.
from src.get_feature_names import get_feature_names
# Set inline graphs
plt.style.use('seaborn')
%matplotlib inline
%config InlineBackend.figure_format = 'retina'
Import the Data
First, we want to import the data:
# Import data
df_train = pd.read_csv("./data/raw/train.csv")
df_test = pd.read_csv("./data/raw/test.csv") # NO y-variable in this df!

print(f"Training data (row x columns): {np.shape(df_train)} \n Testing data (row x columns): {np.shape(df_test)}")
Training data (row x columns): (1460, 81)
Testing data (row x columns): (1459, 80)
Here, it is important to note that the df_test does not contain the y-variable! It should mimic completely new data, on which we will make predictions at the very end of this notebook!
# Select the features
X_train = df_train.drop(['SalePrice'], axis=1) # Select the 'X'-variables --> drop the 'y-variable' (= target)
X_test = df_test

# Check size
print(f"Training features (row x columns): {np.shape(X_train)} \n Testing features (row x columns): {np.shape(X_test)}")
Training features (row x columns): (1460, 80)
Testing features (row x columns): (1459, 80)
The training data also includes the target variable SalePrice, while, as usual, the testing data does not. We need to separate the training data into two parts:
X: the featuresy: the target
# Select the target
y_train = df_train['SalePrice']

# Check size
print(f"Training target: {np.shape(y_train)}")
Training target: (1460,)
It’s good practice to immediately set aside a validation sample with 20% of the training data. The purpose of the validation sample is to give us unbiased estimate of the prediction score. Therefore, we want to set it aside as soon as possible, not to be conditioned in any way by it. Possibly, set it away even before data exploration.
The more we tune the algorithm based on the feedback received from the validation sample, the more biased our estimate is going to be. Ideally, one would use only cross-validation on the training data and tune only a couple of times using the validation data.
# Set aside the validation sample
X_train, X_validation, y_train, y_validation = train_test_split(X_train, y_train, test_size=0.2)
Now we are ready to build and test our pipeline.
Note that X_train does now contain 20% less data, relative to the begininning, after we loaded the data (due to train_test_split()-method!
Data Exploration
X_train.head()
        Id  MSSubClass MSZoning  ...  YrSold  SaleType SaleCondition
186    187          80       RL  ...    2009        WD        Normal
328    329          75       RL  ...    2009        WD        Normal
502    503          20       RL  ...    2007        WD        Normal
644    645          20       FV  ...    2009       New       Partial
1226  1227          60       RL  ...    2008        WD        Normal

[5 rows x 80 columns]
The Id column is clearly not useful for prediction, let’s drop it from both datasets.
# Drop Id
X_train.drop(["Id"], axis=1, inplace=True)
X_test.drop(["Id"], axis=1, inplace=True)
Now we want to identify categorical and numerical variables.
# Save column types
numerical_cols = list(X_train.describe().columns)
categorical_cols = list(X_train.describe(include=object).columns)
print("There are %i numerical and %i categorical variables" % (len(numerical_cols), len(categorical_cols)))
There are 36 numerical and 43 categorical variables
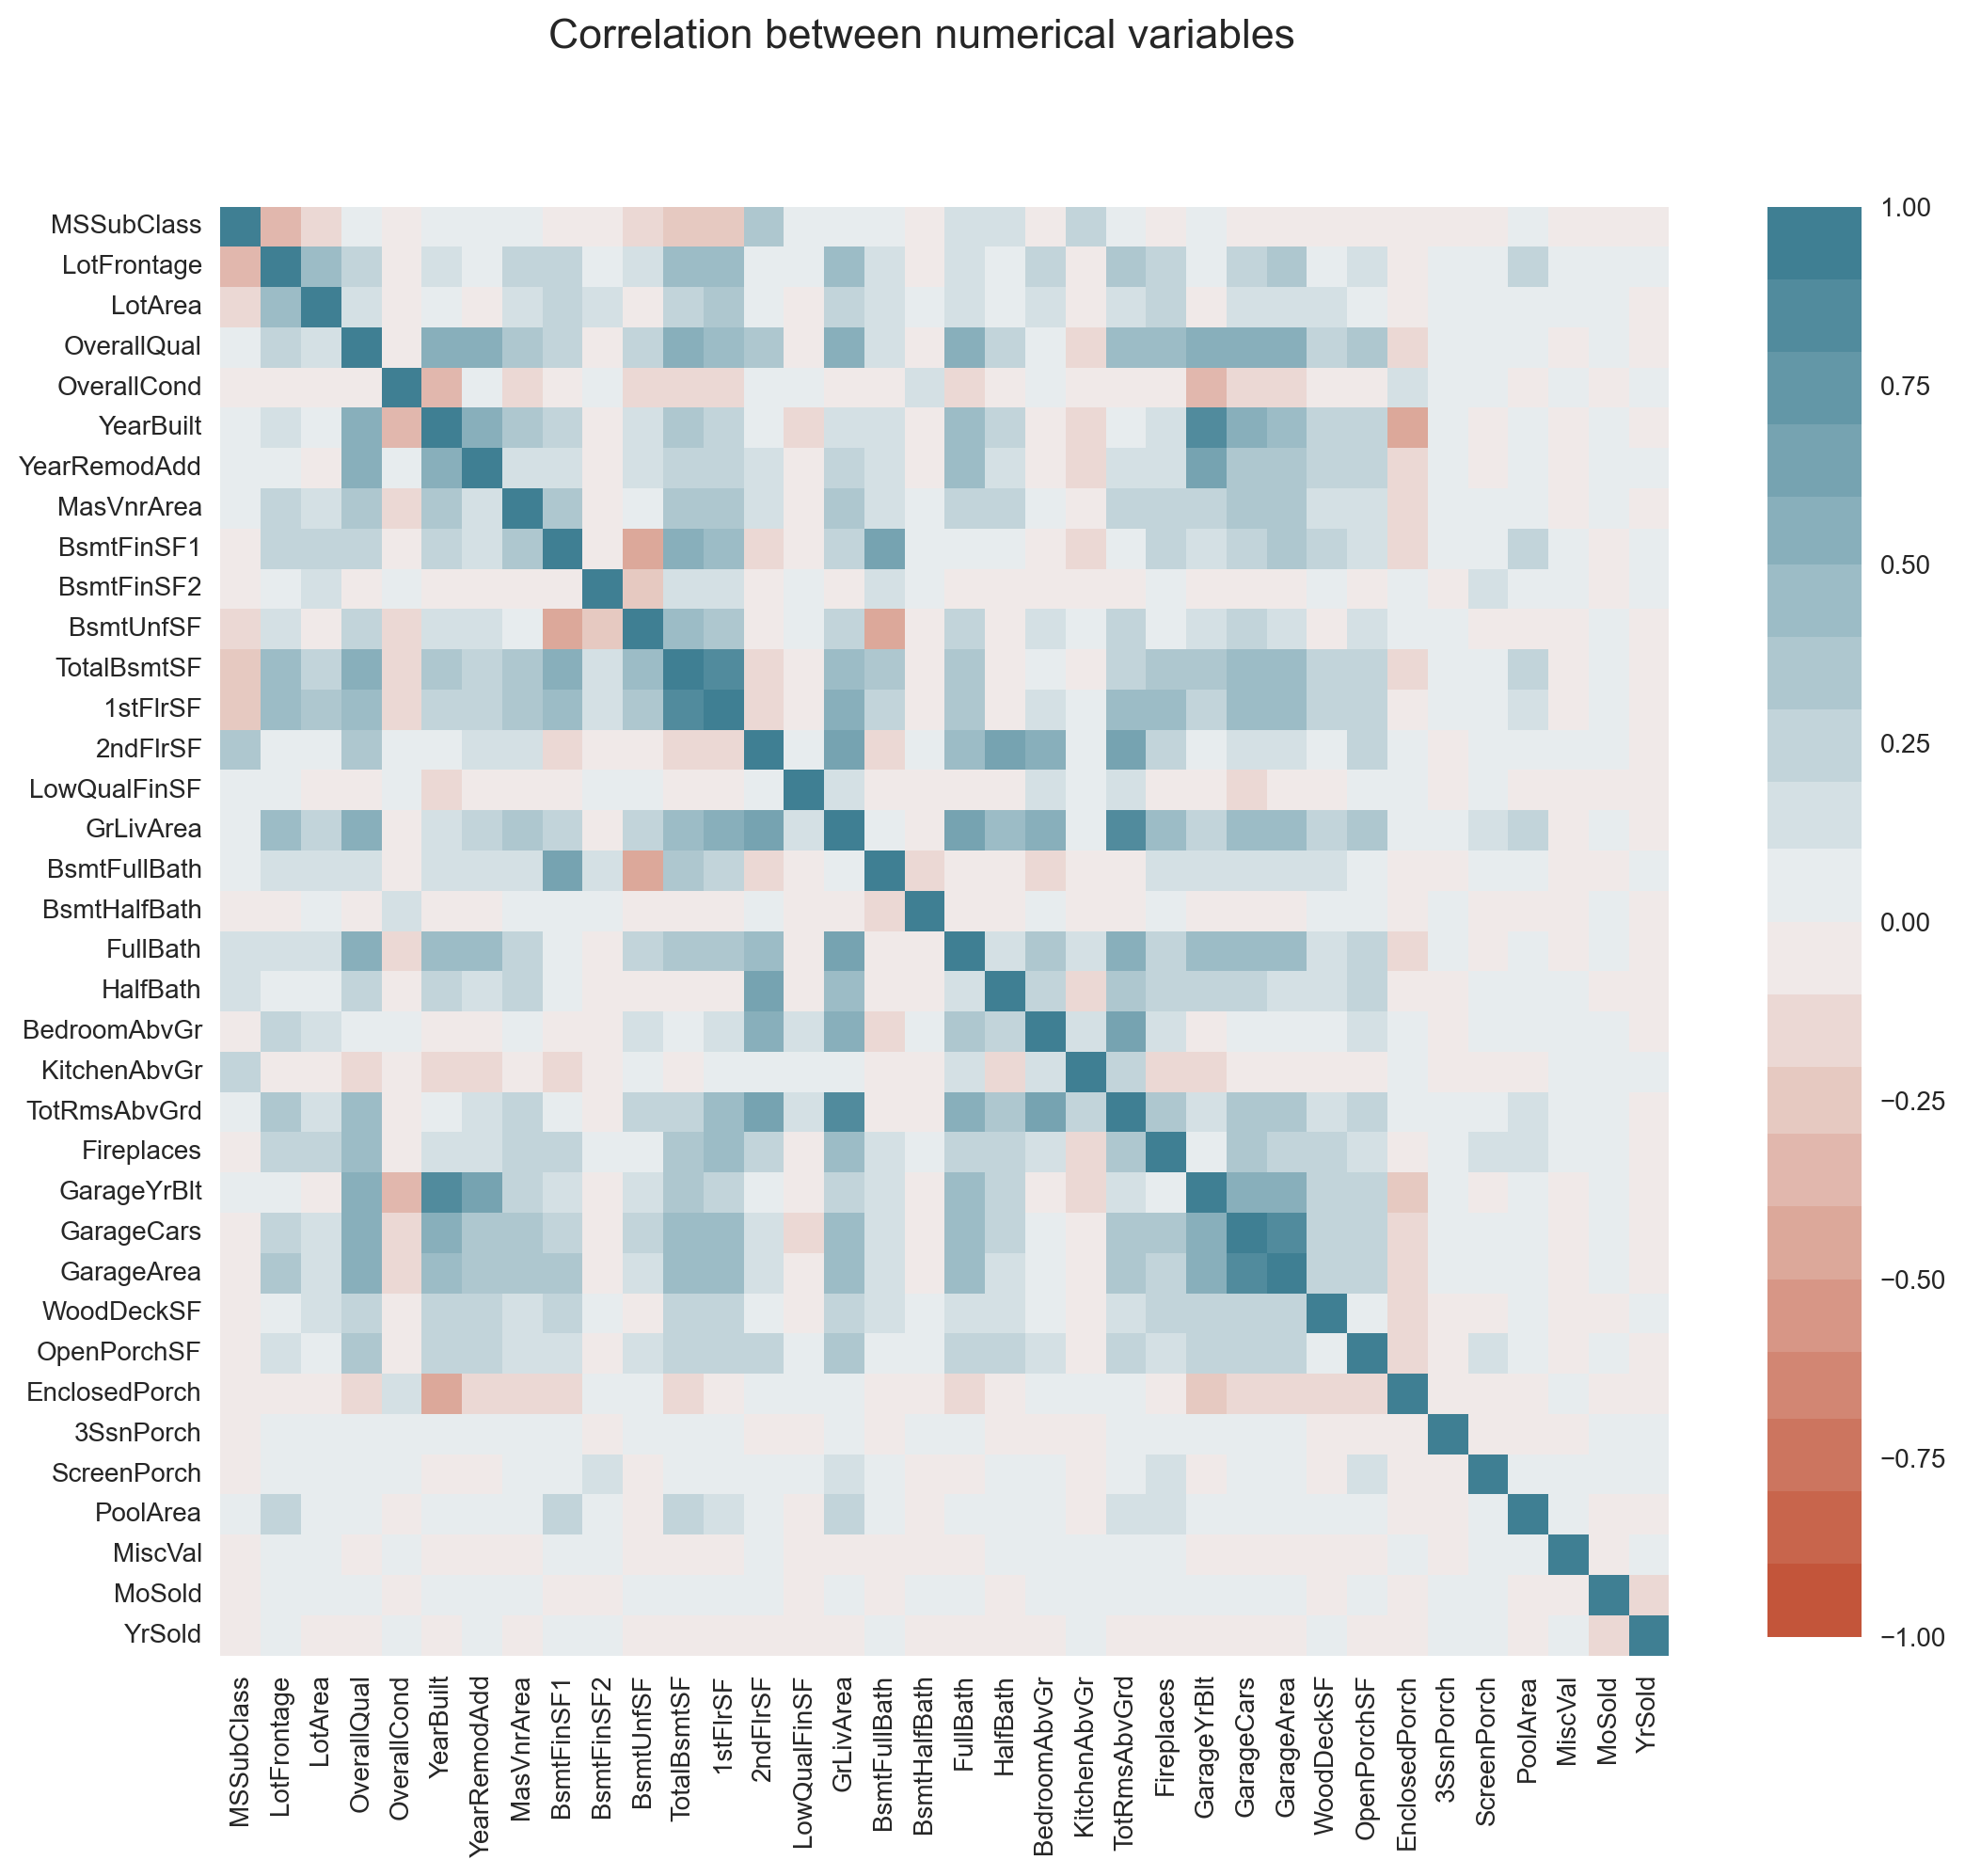
Let’s start by analyzing the numerical variables.
X_numerical = X_train.loc[:, numerical_cols] # "X_numerical" == contains all the numerical variables.
corr = X_numerical.corr()
fig, ax = plt.subplots(1, 1, figsize=(10,10))
fig.suptitle("Correlation between numerical variables", fontsize=16)
cbar_ax = fig.add_axes([.95, .12, .05, .76])
sns.heatmap(corr, vmin=-1, vmax=1, center=0, cmap=sns.diverging_palette(20, 220, n=20),
            square=True, ax=ax, cbar_ax = cbar_ax)
plt.show()
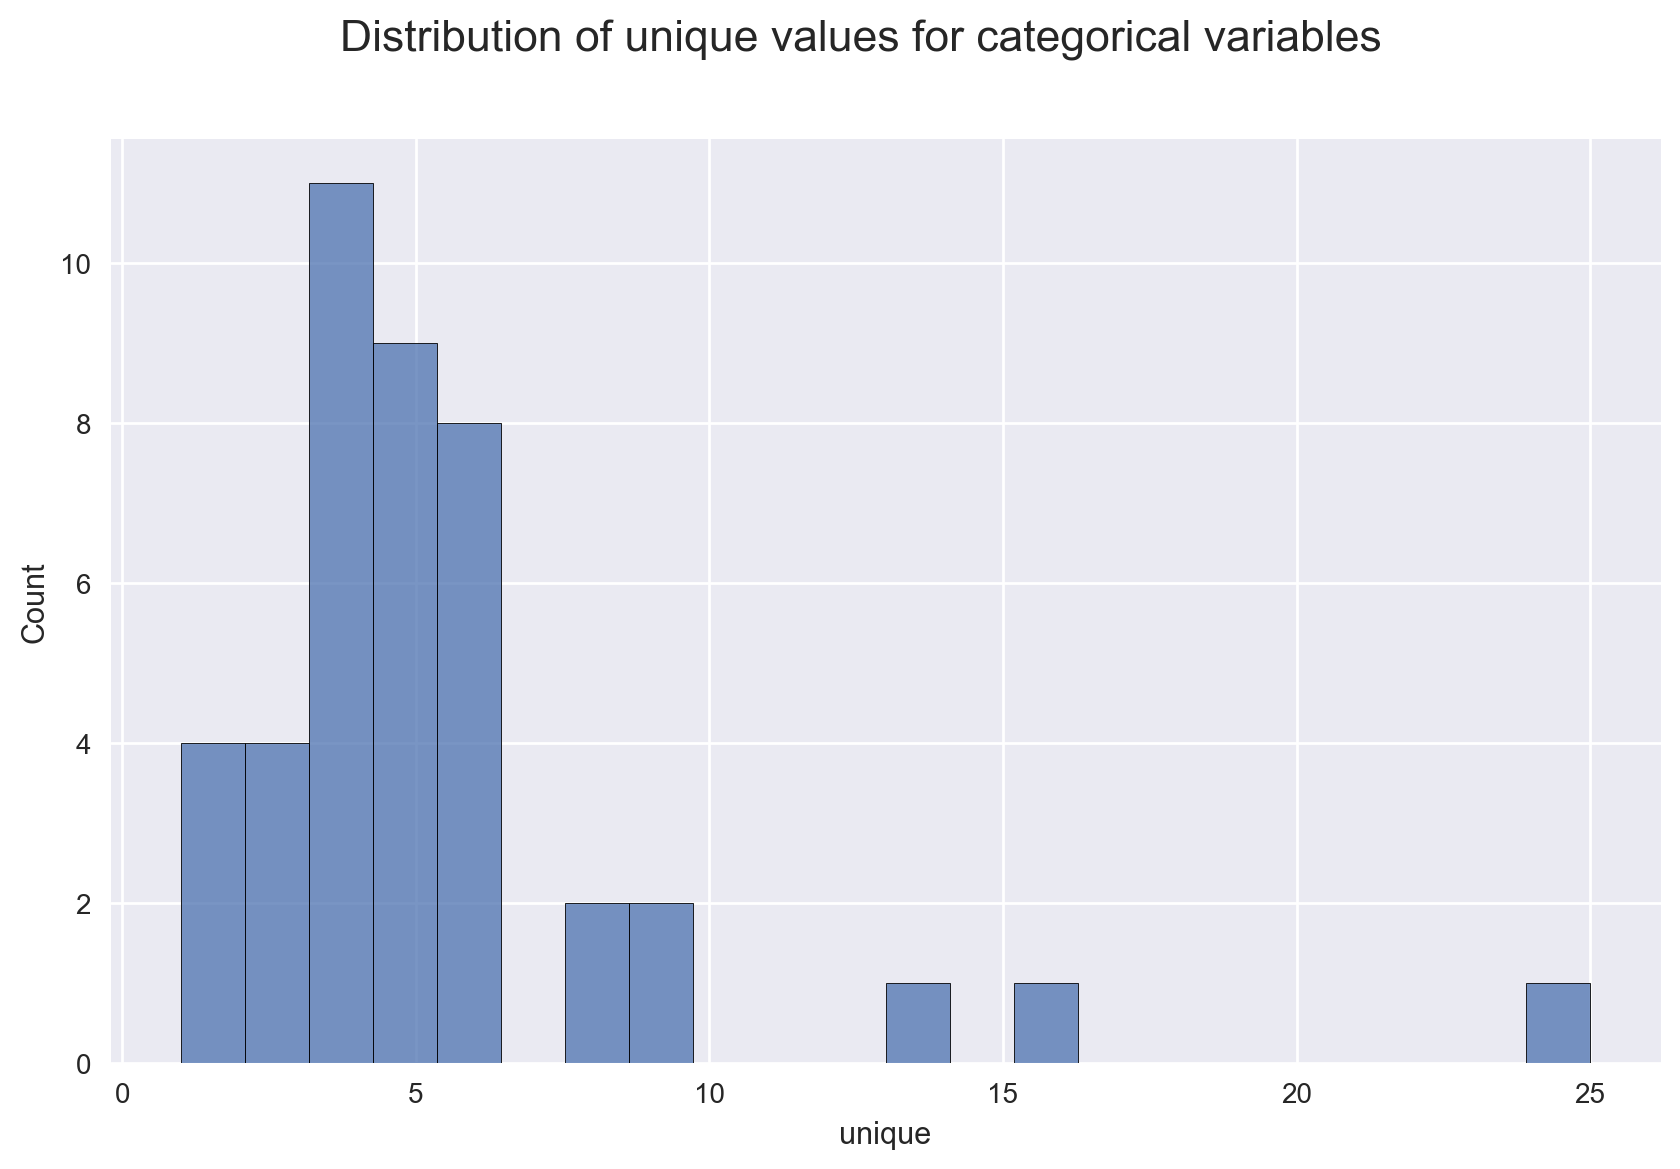
For the non/numeric columns, we need a further option.
unique_values = X_train.describe(include=object).T.unique
unique_values
MSZoning          5
Street            2
Alley             2
LotShape          4
LandContour       4
Utilities         1
LotConfig         5
LandSlope         3
Neighborhood     25
Condition1        9
Condition2        8
BldgType          5
HouseStyle        8
RoofStyle         6
RoofMatl          6
Exterior1st      14
Exterior2nd      16
MasVnrType        4
ExterQual         4
ExterCond         4
Foundation        6
BsmtQual          4
BsmtCond          4
BsmtExposure      4
BsmtFinType1      6
BsmtFinType2      6
Heating           5
HeatingQC         5
CentralAir        2
Electrical        5
KitchenQual       4
Functional        6
FireplaceQu       5
GarageType        6
GarageFinish      3
GarageQual        5
GarageCond        5
PavedDrive        3
PoolQC            3
Fence             4
MiscFeature       4
SaleType          9
SaleCondition     6
Name: unique, dtype: object
# Plot
fig, ax = plt.subplots(1, 1, figsize=(10,6))
fig.suptitle("Distribution of unique values for categorical variables", fontsize=16)
sns.histplot(data=unique_values)
plt.show();
Let’s save the names of the numerical and categorical columns.
# Save column by types (either cat. or numerical) --> key: here, we save each of the column-names!
numerical_cols = list(X_train.describe().columns)
categorical_cols = list(X_train.describe(include=object).columns)
# categorical_cols # check: should output all of the names of all categorical columns --> ['MSZoning', 'Street', 'Alley', ...]
How many missing values are there in the dataset?
missing_values = X_train.isnull().sum().sort_values(ascending=True)[-20:] / len(X_train)
fig, ax = plt.subplots(figsize=(10,8))
ax.set_title("Variables with most missing values", fontsize=16)
ax.barh(np.arange(len(missing_values)), missing_values)
ax.set_yticks(np.arange(len(missing_values)))
ax.set_yticklabels(missing_values.index)
ax.set_xlabel('Percentage of missig values')
plt.show()
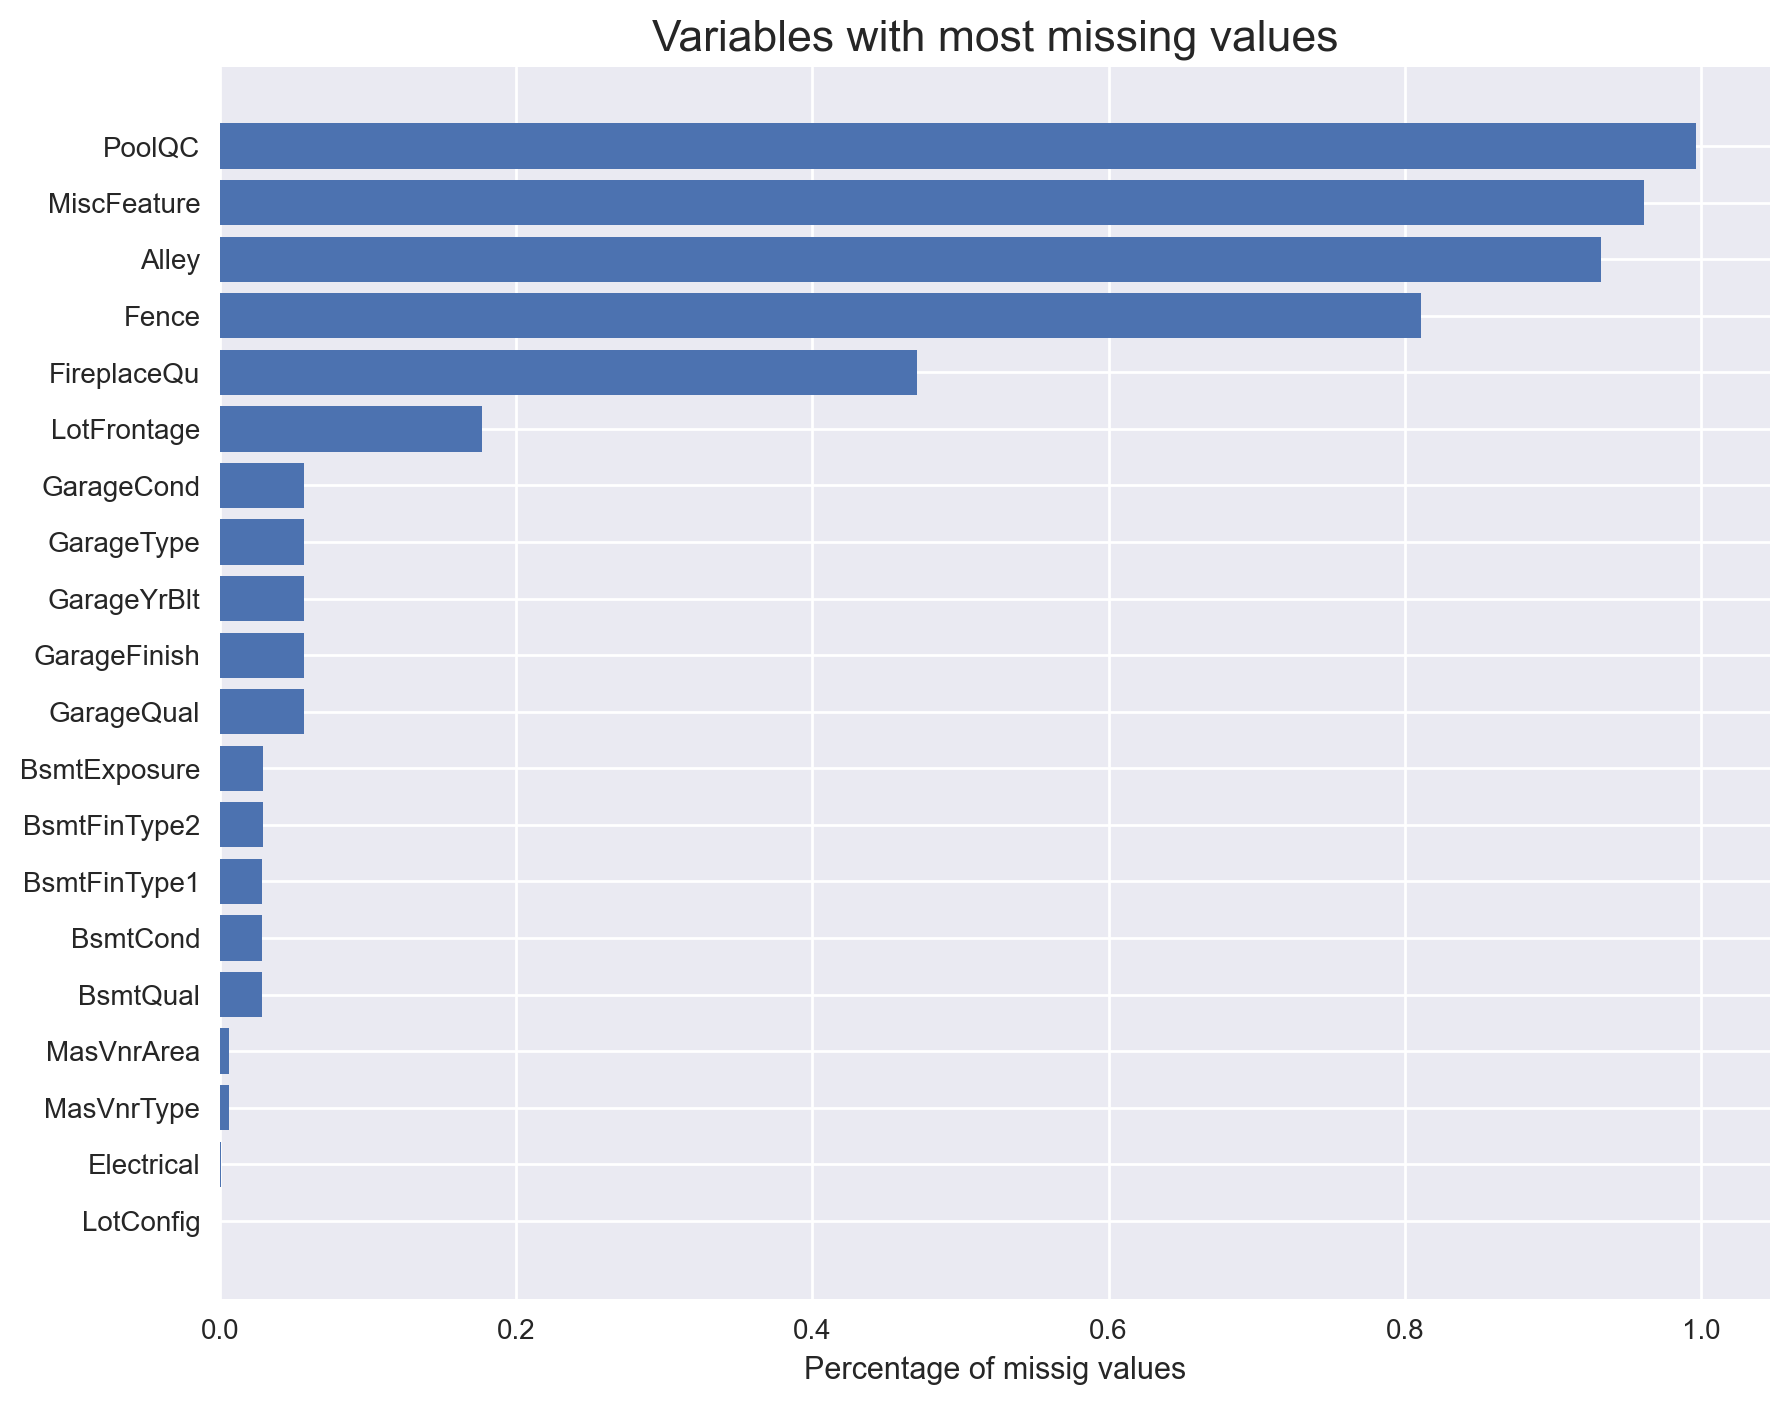
Around 10% of each feature is missing. We will have to deal with that.
Pre-Processing
First, let’s process the numerical variables. We want to do two things:
- impute missing values
- standardize all variables, e.g. scaling the (numerical) variables.
In that order!
Imputation
Which imputer should to use?
It depends on the type of missing data:
-
Missing absolutely at random: as the name says, in this case we believe that missing values are distributed uniformly at random, independently across variables.
- In this case, the only information on missing values comes from the distribution of non-missing values of the same variable.
- No information on missing values is contained in other variables.
-
Missing at random: in this case, missing values are random, conditional on values of other observed variables.
- In this case, information in other variables might help filling missing values.
-
Missing non at random: in this last case, missing values depend on information that we do not observe.
- This is the most tricky category of missing values since data alone does not tell us which values might be missing. For example, we might have that older women might be less likely to report the age.
- If we consider the data missing at random (absolutely or not), we would underestimate the missing ages.
- External information such as the sample population might help. For example, we could estimate the probability of not reporting the age and fill the missing values with the expected age, conditional on age not being reported.
So, which imputers are readily available in sklearn for numerical data?
For data missing absolutely at random, there is one standard sklearn library: SimpleImputer(). It allows different strategy options such as
"mean""median""most_frequent"
For data missing at random, there are multiple sklearn libraries:
KNNImputer(): uses KNNIterativeImputer(): uses a variety of ML algorithms- see comparison here
Standardize
After we have inputed missing values, we want to standardize numerical variables to make the algorithm more efficient AND robust to outliers.
The two main options for standardization are:
StandardScaler(): which normalizes each variable to mean zero and unit varianceMinMaxScaler(): which normalizes each variable to an interval between zero an one
# Pipeline for numerical variables: Imputer + Scaling (e.g. take the standard normal)
num = Pipeline(steps=[
    ('ii', IterativeImputer()),
    ('ss', StandardScaler())
    ])
For categorical variables, we do not have to worry about scaling (= “standardization”). However, we still need to impute missing values and, crucially, we need to transform them into numerical variables. This process is called encoding.
Which imputer should to use for categorical variables?
For data missing absolutely at random, the only available strategy option for SimpleImputer() is:
"most frequent"
For data missing at random, we can still use both
KNNImputer()IterativeImputer()
For encoding categorical variables (= creating dummy-variables), the standard option is OneHotEncoder() which generates unique binary variables - which is basically a dummy with a value 1 or 0 - out of every values of the categorical variable.
# Pipeline for categorical(!) variables: Imputing & One Hot Encoder
cat = Pipeline(steps=[
    ('si', SimpleImputer(strategy="most_frequent")),
    ('ohe', OneHotEncoder(handle_unknown="ignore")),
    ])
Put the (pre-processor) Pipeline together
# Preprocess column transformer for preprocessing data
preprocess = ColumnTransformer(
                    transformers=[
                        ('num', num, numerical_cols), # preprocessing of all **numerical** columns
                        ('cat', cat, categorical_cols), # preprocessing of all **categorical** columns
                    ])
Information & Components
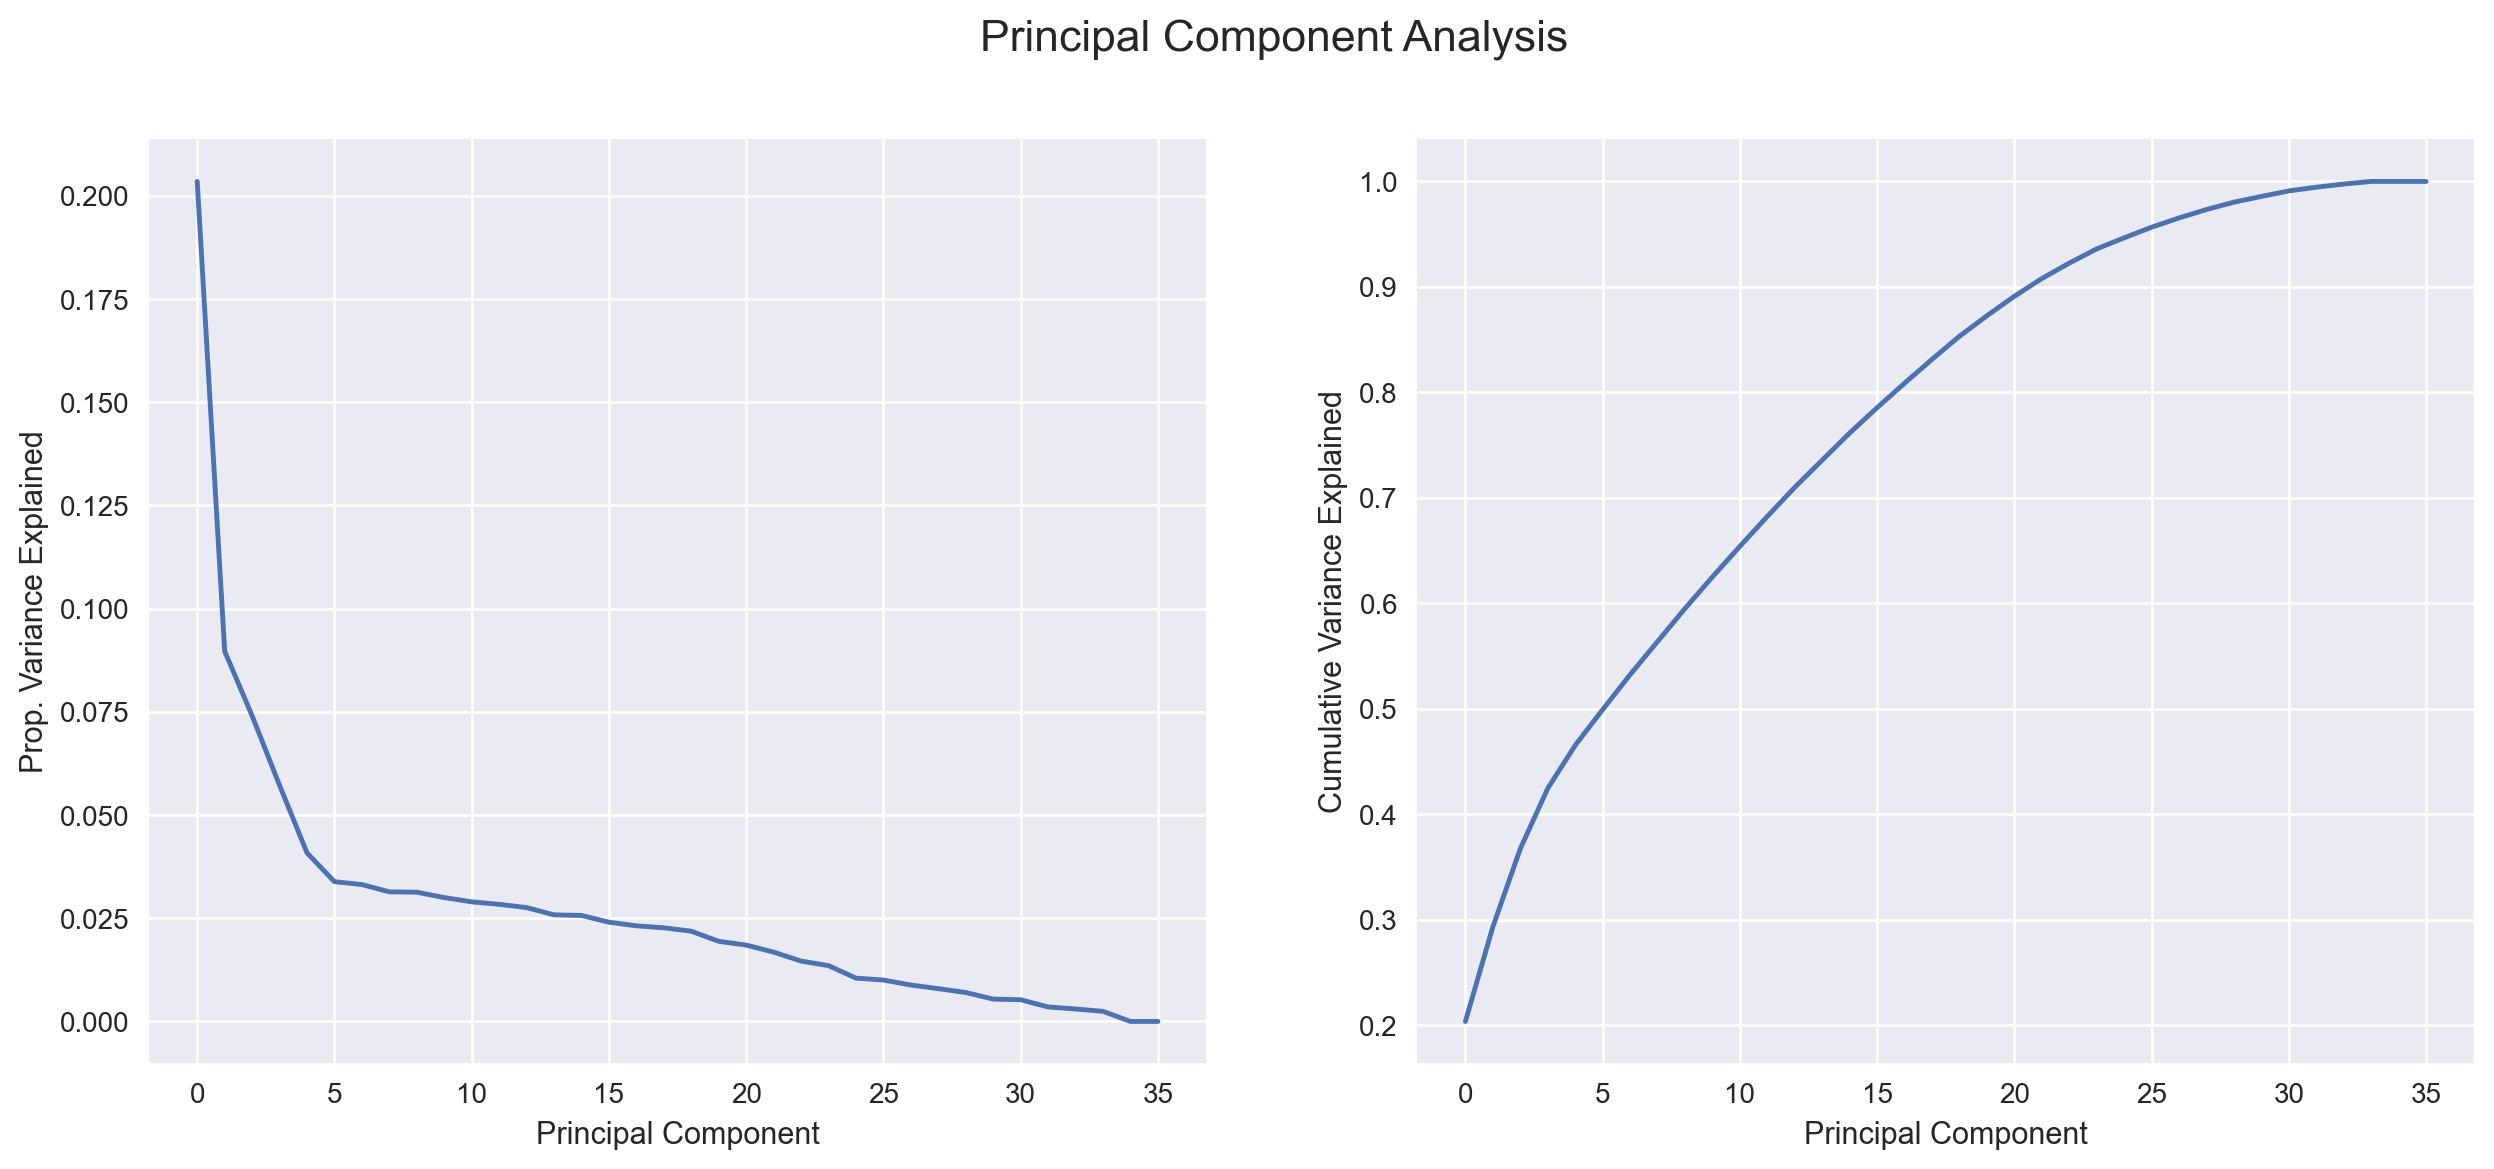
How much information is contained in our dataset? It is a dense or sparse dataset?
X_clean = num.fit_transform(X_numerical) # note: take only the numerical variables for the PCA! -> remember: we had 36 num. variables in total for this df...
pca = PCA().fit(X_clean)
explained_variance = pca.explained_variance_ratio_
fig, (ax1, ax2) = plt.subplots(1,2, figsize=(15,6))
fig.suptitle('Principal Component Analysis', fontsize=16);

# Relative
ax1.plot(range(len(explained_variance)), explained_variance)
ax1.set_ylabel('Prop. Variance Explained')
ax1.set_xlabel('Principal Component');

# Cumulative
ax2.plot(range(len(explained_variance)), np.cumsum(explained_variance))
ax2.set_ylabel('Cumulative Variance Explained');
ax2.set_xlabel('Principal Component');
Feature Importance
Before starting our prediction analysis, we would like to understand which variables are most important for our prediction problem.
# the function below will be called in the "featureimportance_lr()" function
def plot_featureimportance(importance, preprocess):
    df = pd.DataFrame({"names": get_feature_names(preprocess), "values": importance})
    df = df.sort_values("values").iloc[:20, :]
    # plot
    fig, ax = plt.subplots(figsize=(10,8))
    ax.set_title("Feature importance", fontsize=16)
    sns.barplot(y="names", x="values", data=df)
    ax.barh(np.arange(len(df)), df["values"])
    plt.show()
def featureimportance_lr(X, y):
    X_clean = preprocess.fit_transform(X)
    # fit the model
    model = LinearRegression()
    model.fit(X_clean, y)
    # get importance
    importance = np.abs(model.coef_)
    plot_featureimportance(importance, preprocess)
# Plot linear feature importance
featureimportance_lr(X_train, y_train)
---------------------------------------------------------------------------

ValueError                                Traceback (most recent call last)

Cell In[31], line 2
      1 # Plot linear feature importance
----> 2 featureimportance_lr(X_train, y_train)


Cell In[30], line 8, in featureimportance_lr(X, y)
      6 # get importance
      7 importance = np.abs(model.coef_)
----> 8 plot_featureimportance(importance, preprocess)


Cell In[29], line 3, in plot_featureimportance(importance, preprocess)
      2 def plot_featureimportance(importance, preprocess):
----> 3     df = pd.DataFrame({"names": get_feature_names(preprocess), "values": importance})
      4     df = df.sort_values("values").iloc[:20, :]
      5     # plot


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/frame.py:664, in DataFrame.__init__(self, data, index, columns, dtype, copy)
    658     mgr = self._init_mgr(
    659         data, axes={"index": index, "columns": columns}, dtype=dtype, copy=copy
    660     )
    662 elif isinstance(data, dict):
    663     # GH#38939 de facto copy defaults to False only in non-dict cases
--> 664     mgr = dict_to_mgr(data, index, columns, dtype=dtype, copy=copy, typ=manager)
    665 elif isinstance(data, ma.MaskedArray):
    666     import numpy.ma.mrecords as mrecords


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:493, in dict_to_mgr(data, index, columns, dtype, typ, copy)
    489     else:
    490         # dtype check to exclude e.g. range objects, scalars
    491         arrays = [x.copy() if hasattr(x, "dtype") else x for x in arrays]
--> 493 return arrays_to_mgr(arrays, columns, index, dtype=dtype, typ=typ, consolidate=copy)


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:118, in arrays_to_mgr(arrays, columns, index, dtype, verify_integrity, typ, consolidate)
    115 if verify_integrity:
    116     # figure out the index, if necessary
    117     if index is None:
--> 118         index = _extract_index(arrays)
    119     else:
    120         index = ensure_index(index)


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:666, in _extract_index(data)
    664 lengths = list(set(raw_lengths))
    665 if len(lengths) > 1:
--> 666     raise ValueError("All arrays must be of the same length")
    668 if have_dicts:
    669     raise ValueError(
    670         "Mixing dicts with non-Series may lead to ambiguous ordering."
    671     )


ValueError: All arrays must be of the same length
We now look at regression tree feature importance.
def featureimportance_forest(X, y):
    X_clean = preprocess.fit_transform(X)
    # fit the model
    model = RandomForestRegressor()
    model.fit(X_clean, y)
    # get importance
    importance = model.feature_importances_
    plot_featureimportance(importance, preprocess)
# Plot tree feature importance
featureimportance_forest(X_train, y_train)
---------------------------------------------------------------------------

ValueError                                Traceback (most recent call last)

Cell In[33], line 2
      1 # Plot tree feature importance
----> 2 featureimportance_forest(X_train, y_train)


Cell In[32], line 8, in featureimportance_forest(X, y)
      6 # get importance
      7 importance = model.feature_importances_
----> 8 plot_featureimportance(importance, preprocess)


Cell In[29], line 3, in plot_featureimportance(importance, preprocess)
      2 def plot_featureimportance(importance, preprocess):
----> 3     df = pd.DataFrame({"names": get_feature_names(preprocess), "values": importance})
      4     df = df.sort_values("values").iloc[:20, :]
      5     # plot


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/frame.py:664, in DataFrame.__init__(self, data, index, columns, dtype, copy)
    658     mgr = self._init_mgr(
    659         data, axes={"index": index, "columns": columns}, dtype=dtype, copy=copy
    660     )
    662 elif isinstance(data, dict):
    663     # GH#38939 de facto copy defaults to False only in non-dict cases
--> 664     mgr = dict_to_mgr(data, index, columns, dtype=dtype, copy=copy, typ=manager)
    665 elif isinstance(data, ma.MaskedArray):
    666     import numpy.ma.mrecords as mrecords


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:493, in dict_to_mgr(data, index, columns, dtype, typ, copy)
    489     else:
    490         # dtype check to exclude e.g. range objects, scalars
    491         arrays = [x.copy() if hasattr(x, "dtype") else x for x in arrays]
--> 493 return arrays_to_mgr(arrays, columns, index, dtype=dtype, typ=typ, consolidate=copy)


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:118, in arrays_to_mgr(arrays, columns, index, dtype, verify_integrity, typ, consolidate)
    115 if verify_integrity:
    116     # figure out the index, if necessary
    117     if index is None:
--> 118         index = _extract_index(arrays)
    119     else:
    120         index = ensure_index(index)


File ~/Documents/Programming/04-DS-repos/Python/building-ml-pipeline/ml-env/lib/python3.10/site-packages/pandas/core/internals/construction.py:666, in _extract_index(data)
    664 lengths = list(set(raw_lengths))
    665 if len(lengths) > 1:
--> 666     raise ValueError("All arrays must be of the same length")
    668 if have_dicts:
    669     raise ValueError(
    670         "Mixing dicts with non-Series may lead to ambiguous ordering."
    671     )


ValueError: All arrays must be of the same length
Weighting
Another important check to perform concerns weighting.
Is the distribution of our objective variable the same in the training and in the test sample?
If it is not the case, we might get a poor performance just because our training sample is not representative of our testing sample.
This is something that usually we cannot test, since we do not have access to the distribution of the target variable in the test data. However, we might be given the information ex-ante as a warning.
In this case, we perform the analysis on the validation set. Since we have selected the validation set at random, we do not expect significant differences.
fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(15,6))

# Plot 1
sns.histplot(data=y_train, kde=True, ax=ax1)
sns.histplot(data=y_validation, kde=True, ax=ax1, color='orange')
ax1.set_title("Density Function of y", fontsize=16);
ax1.legend(['y train', 'y validation'])

# Plot 2
sns.histplot(data=y_train,  element="step", fill=False,
    cumulative=True, stat="density", common_norm=False, ax=ax2)
sns.histplot(data=y_validation, element="step", fill=False,
    cumulative=True, stat="density", common_norm=False, ax=ax2, color='orange')
ax2.set_title("Cumulative Distribution of y", fontsize=16);
ax2.legend(['y train', 'y validation']);
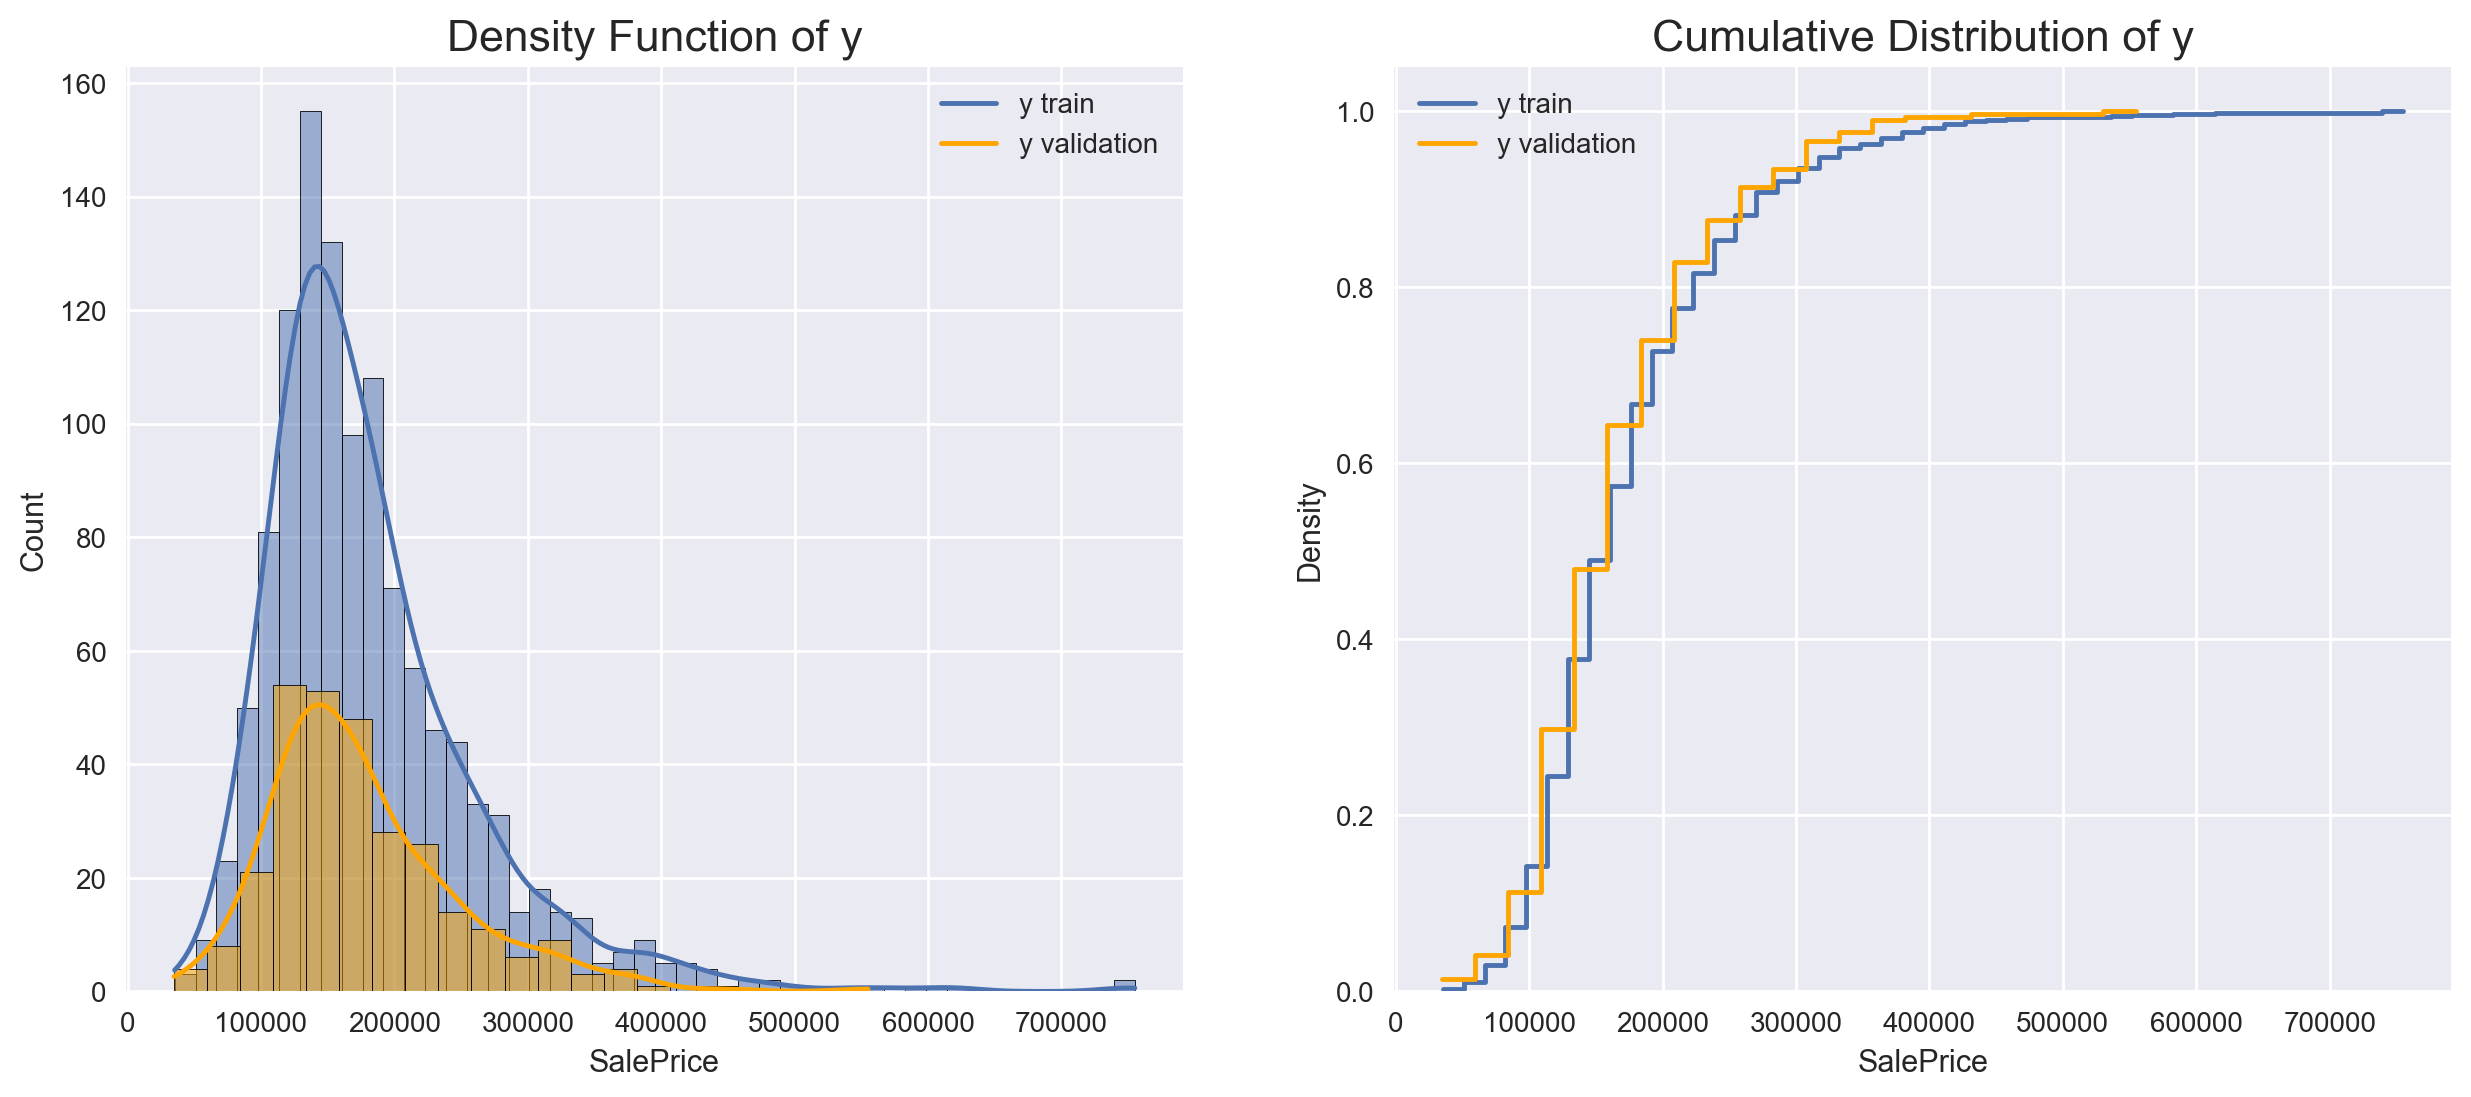
Since the size of the test sample (= our validation set) is smaller than the size of the training sample, the two densities are different (see right graph). However, the distributions indicate that the standardized distributions are the same (see left graph).
Model
# prepare models
models = {"Lasso": Lasso(alpha=100),
          "Ridge": BayesianRidge(),
          "KNN": KNeighborsRegressor(),
          "Kernel": KernelRidge(),
          "Naive": GaussianNB(),
          "SVM": SVR(),
          "Ada": AdaBoostRegressor(),
          "Tree": DecisionTreeRegressor(),
          "Forest": RandomForestRegressor(),
          "GBoost": GradientBoostingRegressor(),
          "XGBoost": XGBRegressor(),
          "LGBoost": LGBMRegressor()}
def evaluate_model(model, name, X, y, cv, scoring):
    X_clean = preprocess.fit_transform(X)
    start = time.perf_counter()
    cv_results = cross_val_score(model, X_clean, y, cv=cv, scoring=scoring)
    t = time.perf_counter()-start
    score = {"model":name, "mean":-np.mean(cv_results), "std":np.std(cv_results), "time":t}
    print("%s: %f (%f) in %f seconds" % (name, -np.mean(cv_results), np.std(cv_results), t))
    return score
def plot_model_scores(scores):
    fig, (ax1, ax2) = plt.subplots(1, 2, figsize=(15,6))
    fig.suptitle("Comparing algorithms", fontsize=16)

    # Plot 1
    scores.sort_values("mean", ascending=False, inplace=True)
    ax1.set_title("Mean squared error", fontsize=16)
    ax1.barh(range(len(scores)), scores["mean"], xerr=scores["std"])
    ax1.set_yticks(range(len(scores)))
    ax1.set_yticklabels([s for s in scores["model"]])

    # Plot 2
    scores.sort_values("time", ascending=False, inplace=True)
    ax2.set_title("Time", fontsize=16)
    ax2.barh(range(len(scores)), scores["time"], color='tab:orange')
    ax2.set_yticks(range(len(scores)))
    ax2.set_yticklabels([s for s in scores["model"]])
    plt.show()
def compare_models(models): # this will call "evaluate_model()"
    scores = pd.DataFrame()
    cv = KFold(n_splits=5) # we will do a 5-fold CV.
    scoring = 'neg_mean_squared_error'
    for name, model in models.items(): # here, we iterate through our whole list of models above
        score = evaluate_model(model, name, X_validation, y_validation, cv, scoring) # note: we take our validation df!
        scores = scores.append(score, ignore_index=True)
    return scores
scores = compare_models(models)
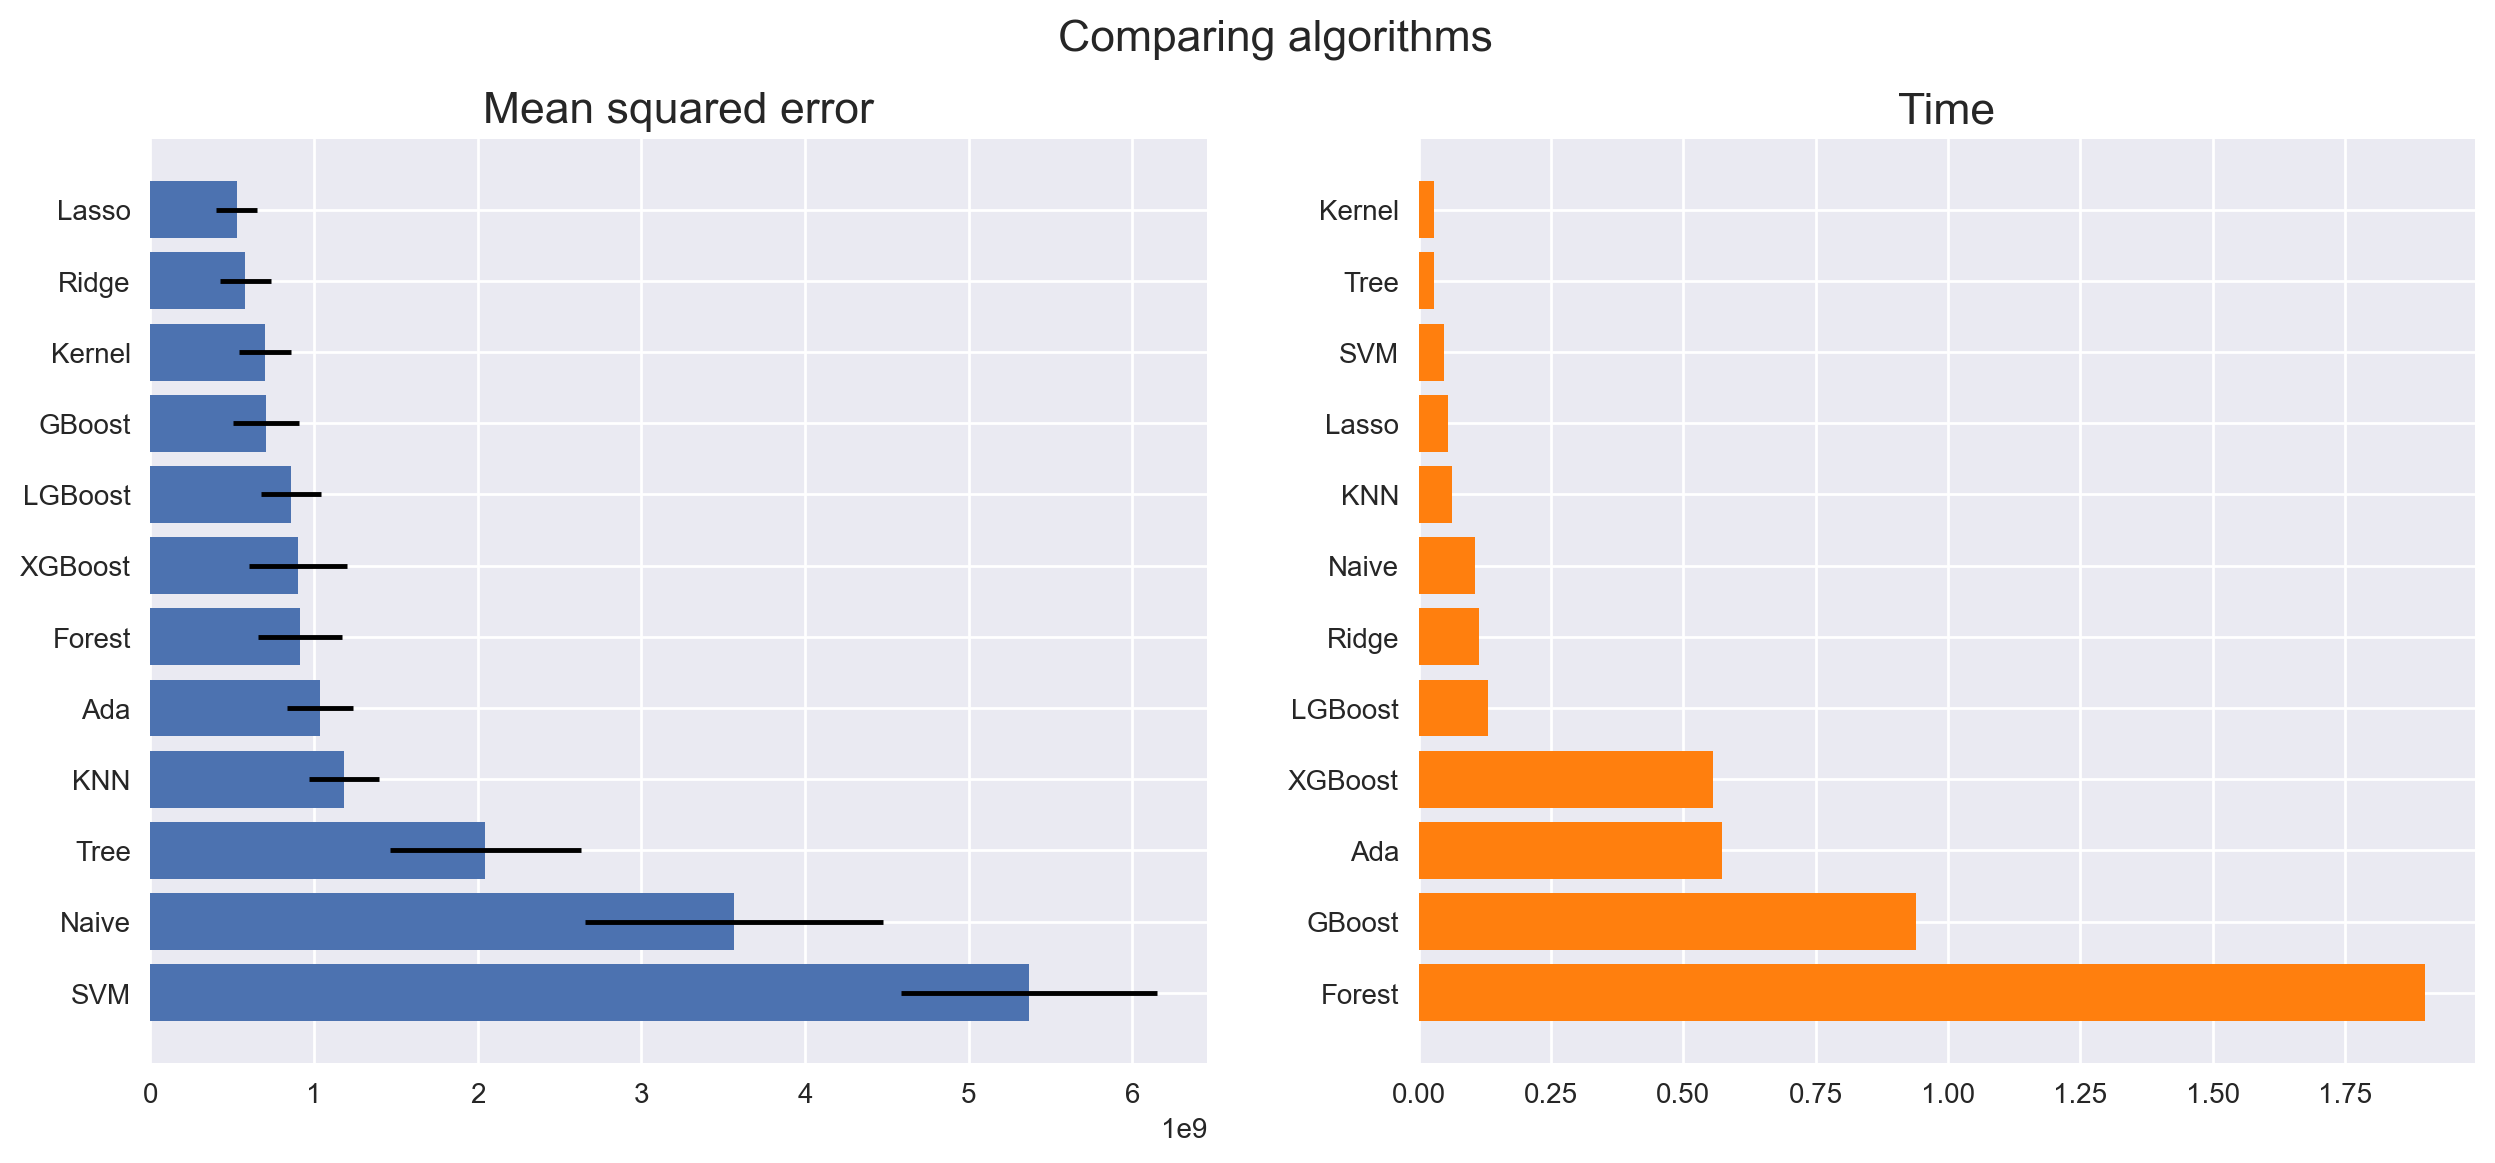
Lasso: 528776305.745608 (124504741.661196) in 0.055880 seconds

Ridge: 579796719.456982 (154861015.814097) in 0.114518 seconds

KNN: 1182051921.709934 (211939673.395566) in 0.063704 seconds

Kernel: 699769270.394520 (160413497.464780) in 0.028967 seconds

Naive: 3564899018.850088 (911289134.306893) in 0.106121 seconds

SVM: 5365814832.489998 (782739246.397673) in 0.048448 seconds

Ada: 1035926358.773750 (203966681.913995) in 0.573172 seconds

Tree: 2046996560.507539 (582953938.894919) in 0.029317 seconds

Forest: 915376685.834388 (255651944.140526) in 1.900519 seconds

GBoost: 705530192.396676 (201369271.166880) in 0.939271 seconds

XGBoost: 900961292.807361 (299152551.279189) in 0.556108 seconds

LGBoost: 859441237.972966 (184073205.736722) in 0.130994 seconds
plot_model_scores(scores)
Pipeline
We are now ready to pick a model.
# Set model
model = LGBMRegressor() # here, we pick the "LGBoost Model"
We need to choose a cross-validation procedure to test our model.
cv = KFold()
Finally, we can combine all the parts into a single pipeline.
final_pipeline = Pipeline(steps=[
        ('preprocess', preprocess),
        ('model', model)
        ])
Now we can decide which parts of the pipeline to test.
# Select parameters to explore
param_grid = {'preprocess__num__ii': [SimpleImputer(), KNNImputer(), IterativeImputer()],
              'preprocess__cat__si__strategy': ["most_frequent", "constant"],
              'model__learning_rate': [0.1, 0.2],
              'model__subsample': [1.0, 0.5],
              'model__max_depth': [30, -1]}
We now generate a grid of parameters we want to search over.
# Instantiate a grid search & save the pipeline
grid_search = GridSearchCV(final_pipeline,
                           param_grid,
                           cv=cv,
                           n_jobs=-1,
                           scoring='neg_mean_squared_error',
                           verbose=3)
Next, we fit the pipeline and pick the best estimator, from the cross-validation score.
# Fit pipeline
grid_search.fit(X_train, y_train)
grid_search.best_estimator_
Fitting 5 folds for each of 48 candidates, totalling 240 fits
We have three ways of testing the quality of fit of our model:
- score on the training data
- score on the validation data
- score on the test data
Score on the training data: this is a biased score since we have picked the model that was best fitting the training data. Kfold cross-validation is efficient in terms of data use, but still evaluates the model over the same data it was trained.
# Cross/validation score
y_train_hat = grid_search.best_estimator_.predict(X_train)
train_rmse = mean_squared_error(y_train, y_train_hat, squared=False)
print('RMSE on training data :', train_rmse)
RMSE on training data : 12338.369545590851
Score on the validation data: this is an unbiased score since we have left out this sample exactly for this purpose. However, be aware that the validation score is unbiased on on the first run. Once we change the grid and pick the algorithm based on previous validation data scores, also this score becomes biased.
# Validation set score
y_validation_hat = grid_search.best_estimator_.predict(X_validation)
validation_rmse = mean_squared_error(y_validation, y_validation_hat, squared=False)
print('RMSE on validation data :', validation_rmse)
RMSE on validation data : 24415.940151701234
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-539153189.039 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-565915040.258 total time=   0.7s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2146703960.760 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-555682820.320 total time=   0.7s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-546422196.654 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-806240441.054 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-815444474.214 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1024616937.757 total time=   0.6s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-887906320.892 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2070614637.227 total time=   0.7s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2089469474.806 total time=   0.5s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-539153189.039 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-842055921.713 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1031121607.620 total time=   0.6s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1023045738.531 total time=   0.3s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2097139956.846 total time=   0.6s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1123194747.759 total time=   0.5s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-950581474.196 total time=   0.4s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2674614489.571 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-936795542.948 total time=   0.9s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-812588971.632 total time=   1.1s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-824117198.652 total time=   0.9s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-687415391.723 total time=   0.6s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1127202861.041 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-670582024.084 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-889784304.233 total time=   0.4s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1083481100.068 total time=   0.6s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-731082680.262 total time=   0.3s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-861936419.821 total time=   0.3s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2080100578.721 total time=   0.4s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-863423014.154 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-815444474.214 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1024616937.757 total time=   0.6s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1017975720.746 total time=   0.5s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-863423014.154 total time=   0.3s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2146703960.760 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-555682820.320 total time=   0.7s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-546422196.654 total time=   0.5s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-863423014.154 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-815444474.214 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1024616937.757 total time=   0.7s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-887906320.892 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2070614637.227 total time=   0.6s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2089469474.806 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-937105925.076 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-889784304.233 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1083481100.068 total time=   0.8s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-937106177.204 total time=   0.5s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-824638611.538 total time=   0.4s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1079851711.897 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-903415697.028 total time=   0.8s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2674614489.571 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-824638611.538 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1079851711.897 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-812588971.632 total time=   0.9s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2603948000.249 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-937105925.076 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2553155964.533 total time=   0.4s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-687415391.723 total time=   0.7s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1127202861.041 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-842055921.713 total time=   0.5s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2070614637.227 total time=   0.6s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2089469474.806 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-807433540.729 total time=   0.3s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2124163300.427 total time=   0.3s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-881213701.944 total time=   0.8s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1023045738.531 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2097139956.846 total time=   0.8s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2080100578.721 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-528490545.493 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1023045738.531 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-807433540.729 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2124163300.427 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-792970492.267 total time=   1.0s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-865127851.603 total time=   0.7s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-915898906.032 total time=   0.4s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2610942003.541 total time=   0.8s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2603948000.249 total time=   0.5s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-670582024.084 total time=   0.4s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-889784304.233 total time=   0.4s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1083481100.068 total time=   0.6s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-731082680.262 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2489827010.558 total time=   0.6s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1123194747.759 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-950581474.196 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2674614489.571 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-936795542.948 total time=   0.6s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1123194747.759 total time=   0.5s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2610942003.541 total time=   0.6s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2603948000.249 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1056631093.475 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1017975720.746 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-528490545.493 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1023045738.531 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-539153189.039 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-842055921.713 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-565915040.258 total time=   0.8s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-872779068.427 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-539153189.039 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1056631093.475 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-792970492.267 total time=   1.1s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-865127851.603 total time=   0.8s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-546422196.654 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-806240441.054 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1047399144.021 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-815898227.960 total time=   0.9s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-812588971.632 total time=   1.4s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-681328362.783 total time=   0.8s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-663710943.719 total time=   0.4s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-824323651.345 total time=   0.4s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1089553950.300 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-936795542.948 total time=   0.7s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2601243910.868 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-660154374.238 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-937106177.204 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-681328362.783 total time=   0.6s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2601243910.868 total time=   0.5s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-950581474.196 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2674614489.571 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1071616459.123 total time=   0.5s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-887906320.892 total time=   0.5s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-806240441.054 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1047399144.021 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-815898227.960 total time=   1.1s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2080100578.721 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-528490545.493 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-544672820.052 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-807433540.729 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2124163300.427 total time=   0.4s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-881213701.944 total time=   0.7s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2146703960.760 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-555682820.320 total time=   0.8s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1017975720.746 total time=   0.4s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-863423014.154 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-2146703960.760 total time=   0.3s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-555682820.320 total time=   0.6s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-903415697.028 total time=   0.9s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-731082680.262 total time=   0.4s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2489827010.558 total time=   0.8s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2601243910.868 total time=   0.5s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-950581474.196 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-937106177.204 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1071616459.123 total time=   0.6s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-915898906.032 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-824323651.345 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1089553950.300 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-824117198.652 total time=   1.0s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-812588971.632 total time=   1.0s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-936795542.948 total time=   0.5s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-807433540.729 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-792970492.267 total time=   1.1s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-865127851.603 total time=   0.7s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-887906320.892 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2070614637.227 total time=   0.7s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2089469474.806 total time=   0.4s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-861936419.821 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-842055921.713 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-565915040.258 total time=   0.7s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-544672820.052 total time=   0.5s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-861936419.821 total time=   0.4s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1056631093.475 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-565915040.258 total time=   0.7s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-815444474.214 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-670582024.084 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1079851711.897 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2601243910.868 total time=   0.5s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-660154374.238 total time=   0.5s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-828655957.404 total time=   0.4s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1071616459.123 total time=   0.7s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-915898906.032 total time=   0.4s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2610942003.541 total time=   0.7s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-2603948000.249 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-670582024.084 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-889784304.233 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1083481100.068 total time=   0.5s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-731082680.262 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-824638611.538 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1079851711.897 total time=   0.4s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-903415697.028 total time=   0.7s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-828655957.404 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-681328362.783 total time=   0.5s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-546422196.654 total time=   0.5s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1031121607.620 total time=   0.6s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-872779068.427 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2097139956.846 total time=   0.6s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-792970492.267 total time=   1.1s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-865127851.603 total time=   0.8s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1017975720.746 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-806240441.054 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1047399144.021 total time=   0.3s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-815898227.960 total time=   1.2s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-881213701.944 total time=   0.7s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-872779068.427 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1024616937.757 total time=   0.6s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-663710943.719 total time=   0.5s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-824323651.345 total time=   0.5s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1089553950.300 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-824117198.652 total time=   1.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-687415391.723 total time=   0.7s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1127202861.041 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-937105925.076 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2553155964.533 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-903415697.028 total time=   0.6s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-828655957.404 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-1071616459.123 total time=   0.6s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-663710943.719 total time=   0.5s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-660154374.238 total time=   0.3s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-937106177.204 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2489827010.558 total time=   0.5s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2124163300.427 total time=   0.3s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-881213701.944 total time=   0.7s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-544672820.052 total time=   0.4s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-861936419.821 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-1056631093.475 total time=   0.3s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1031121607.620 total time=   0.6s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1047399144.021 total time=   0.4s
[CV 1/5] END model__learning_rate=0.1, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-815898227.960 total time=   1.2s
[CV 4/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-1031121607.620 total time=   0.6s
[CV 2/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-872779068.427 total time=   0.4s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2097139956.846 total time=   0.8s
[CV 5/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-2080100578.721 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-528490545.493 total time=   0.4s
[CV 3/5] END model__learning_rate=0.1, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-544672820.052 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-824638611.538 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2553155964.533 total time=   0.3s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-687415391.723 total time=   0.9s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-1127202861.041 total time=   0.5s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-937105925.076 total time=   0.4s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=SimpleImputer();, score=-2553155964.533 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-1123194747.759 total time=   0.4s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-660154374.238 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=KNNImputer();, score=-828655957.404 total time=   0.4s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=30, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-681328362.783 total time=   0.7s
[CV 3/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-663710943.719 total time=   0.3s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=IterativeImputer();, score=-2610942003.541 total time=   0.6s
[CV 5/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=1.0, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-2489827010.558 total time=   0.6s
[CV 2/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=most_frequent, preprocess__num__ii=KNNImputer();, score=-915898906.032 total time=   0.5s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-824323651.345 total time=   0.3s
[CV 4/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=SimpleImputer();, score=-1089553950.300 total time=   0.3s
[CV 1/5] END model__learning_rate=0.2, model__max_depth=-1, model__subsample=0.5, preprocess__cat__si__strategy=constant, preprocess__num__ii=IterativeImputer();, score=-824117198.652 total time=   0.7s
Final predictions: we can now use our model to output the predictions.
# Test score
y_test_hat = grid_search.best_estimator_.predict(X_test) # this is completetely **new** data!
y_test_hat
array([128270.84248471, 155702.90571215, 180131.89477202, ...,
       159949.09949117, 119928.26557182, 238091.22813851])
len(y_test_hat)
1459
